Your model is only as secure as the system around it.
AI security assessment for LLM applications and AI agents
Shipping an LLM feature introduces a class of risk your existing security tooling was never built to catch — prompt injection, data exfiltration through model output, and agents that take actions no one reviewed. We help engineering teams find those gaps before an attacker does.
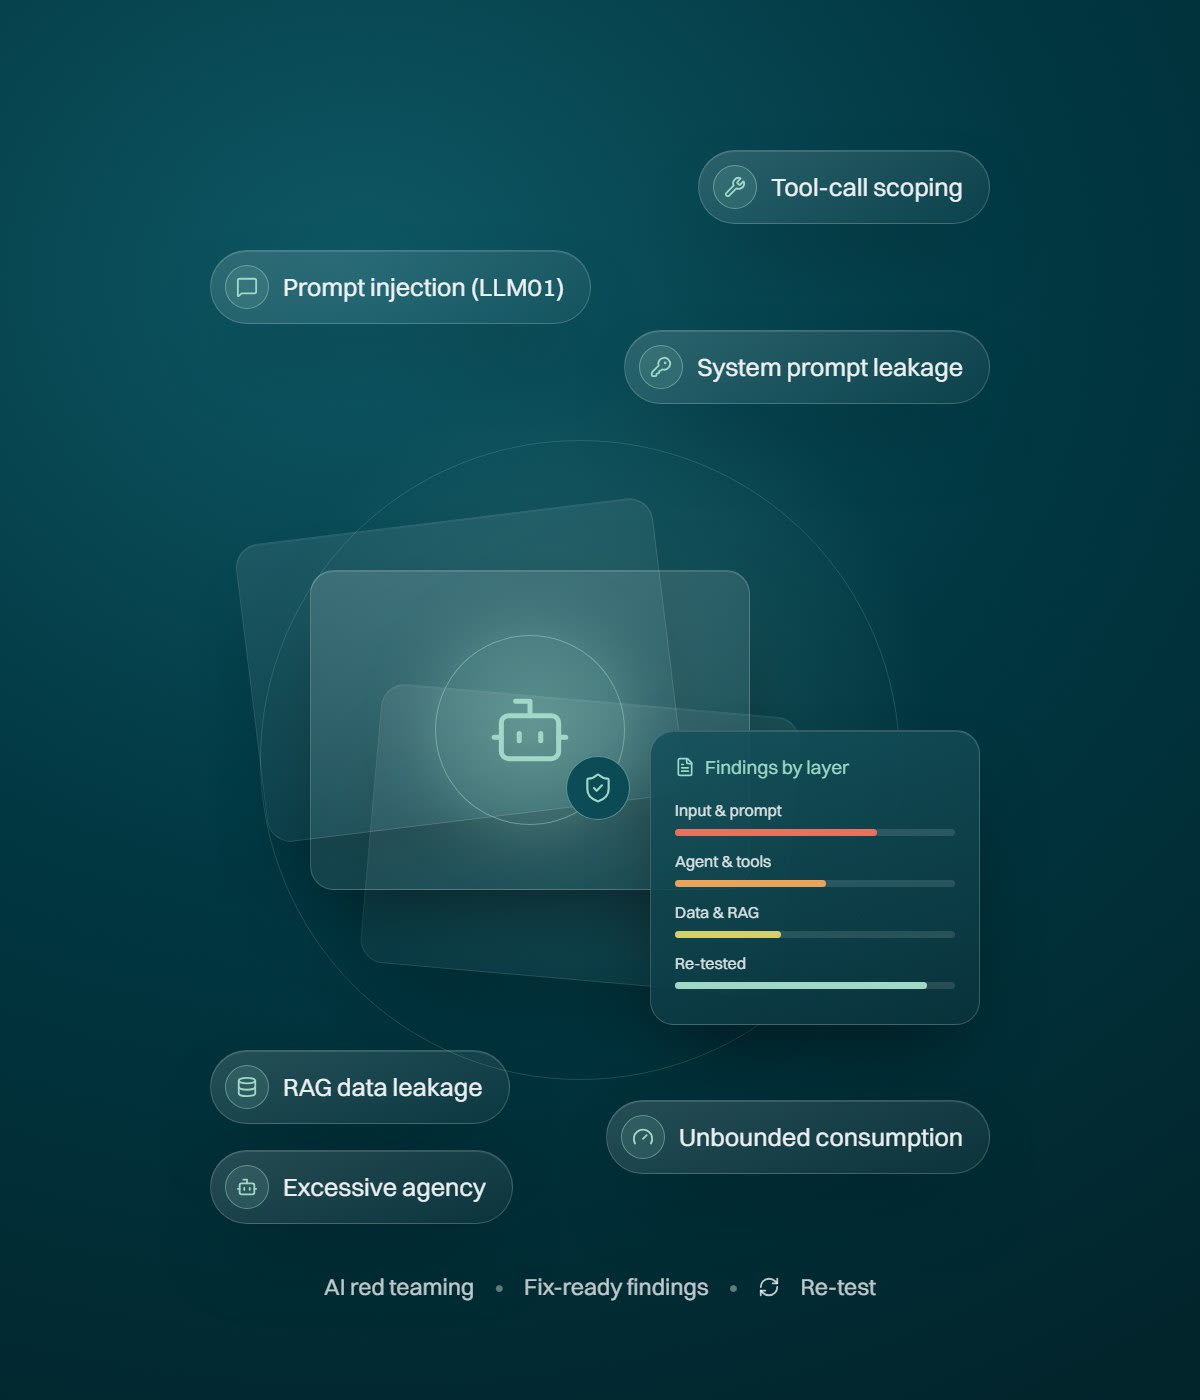
An AI security assessment tests a generative AI or LLM application the way an attacker would: its prompts, the tools and agents it can call, and the data it retrieves. Tizora runs these assessments against the OWASP Top 10 for LLM Applications, then works with your engineers to fix and re-test what we find.
A methodology built around how LLM systems actually fail.
Why LLM applications need their own LLM security testing
A traditional web app has a fixed set of inputs and a predictable code path. An LLM-backed feature doesn’t — it accepts open-ended natural language, often from untrusted users, and turns that input into decisions, database queries, or tool calls. That gap between "what the model was told to do" and "what it can be tricked into doing" is where most AI-specific incidents actually happen, and it sits outside what a conventional penetration test or WAF is designed to catch. We work with engineering teams to close that gap at the architecture level, not just patch individual prompts after something goes wrong. For the code, APIs and infrastructure around the model, pair it with application security testing.
- Location
- Remote-first, global engagements
- Service
- AI security assessment
- Cooperation period
- Point-in-time review or ongoing coverage
- Services used
- LLM red-teaming · RAG & agent security · Guardrail design · Model risk assessment
AI security assessment vs penetration test
| Question | Conventional penetration test | For LLM applicationsAI security assessment |
|---|---|---|
| What is tested | Conventional penetration testApplications, APIs and infrastructure | AI security assessmentThe model, the agent and tool layer, and the data pipeline together |
| Inputs | Conventional penetration testFixed inputs and known endpoints | AI security assessmentOpen-ended natural language, often from untrusted users and documents |
| Typical attacks | Conventional penetration testInjection, broken authentication, misconfiguration | AI security assessmentPrompt injection, jailbreaks, tool-call abuse, data extraction |
| Reference framework | Conventional penetration testOWASP Top 10 for web applications | AI security assessmentOWASP Top 10 for LLM Applications |
| Fixes | Conventional penetration testCode and configuration changes | AI security assessmentArchitecture changes: scoping, validation, retrieval boundaries, confirmation steps |
What an AI security assessment covers
We organize every assessment around the OWASP Top 10 for LLM Applications (2025), mapped to the parts of your stack where each risk actually lives. Shipping a Shopify app as well? See our VAPT for Shopify apps.
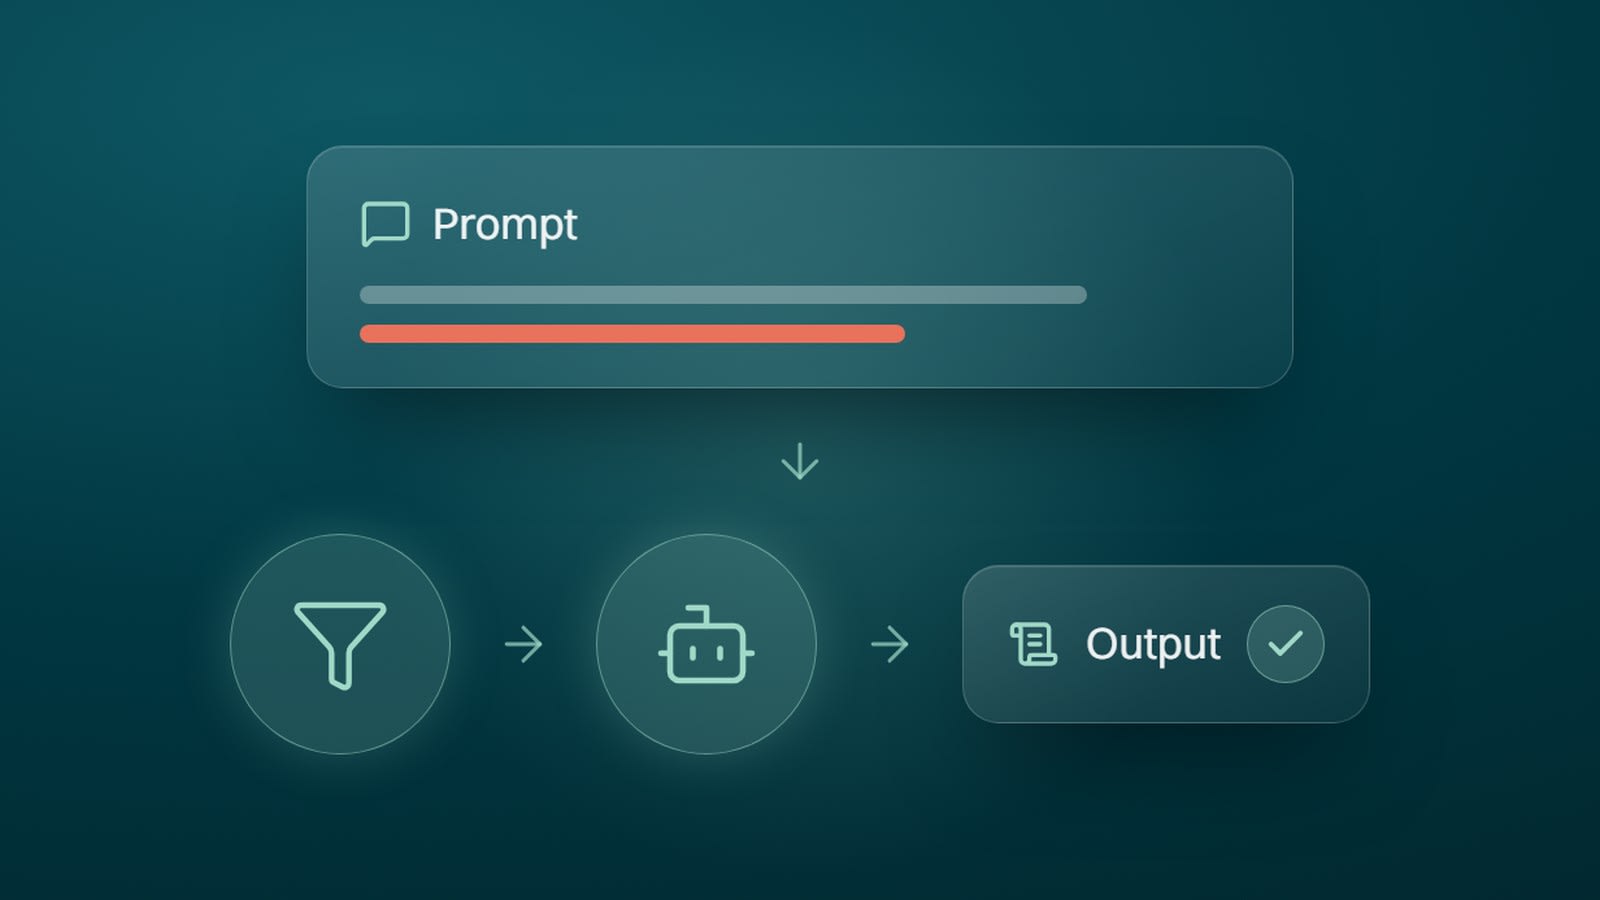
Input and prompt layer
- Prompt injection, direct and indirect (LLM01)
- Jailbreak and guardrail bypass testing
- System prompt leakage (LLM07)
- Improper output handling downstream (LLM05)
Input and prompt layer
The first place AI systems get attacked: direct and indirect prompt injection, jailbreak and guardrail bypass, system prompt leakage, and improper handling of model output downstream.
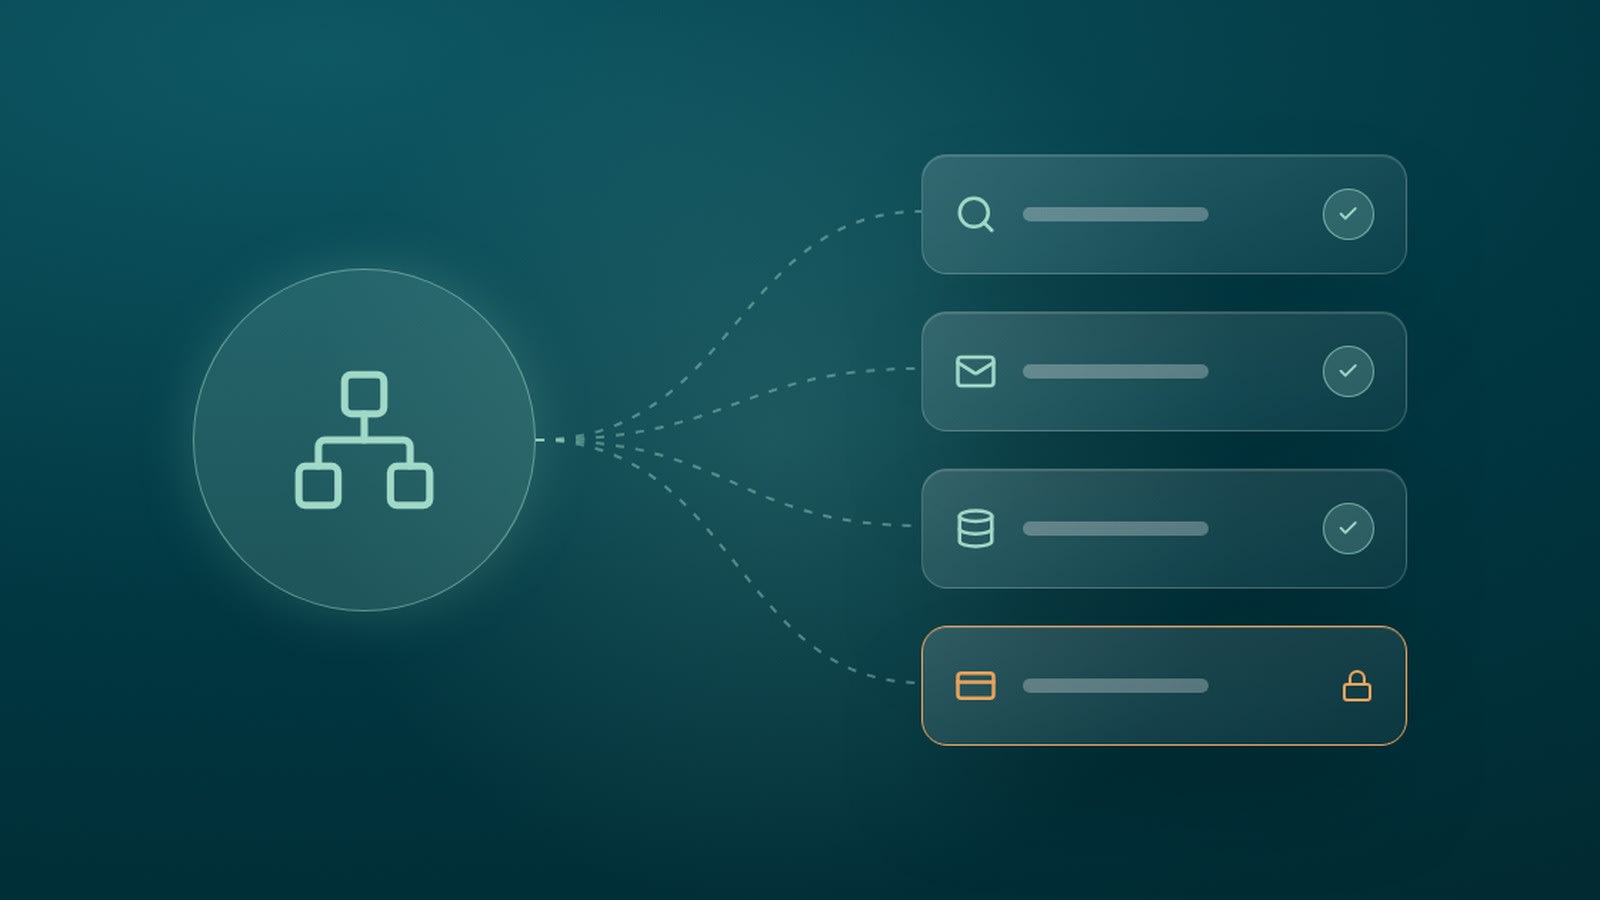
Orchestration and agent layer
- Excessive agency and tool-call scoping (LLM06)
- Tool and function design review
- Human-in-the-loop gate review
- Multi-agent trust boundary mapping
- MCP server and tool connector review
Orchestration and agent layer
Where agents act: excessive agency and tool-call scoping, tool and function design, human-in-the-loop gates, multi-agent trust boundaries, and the MCP servers that connect agents to tools.
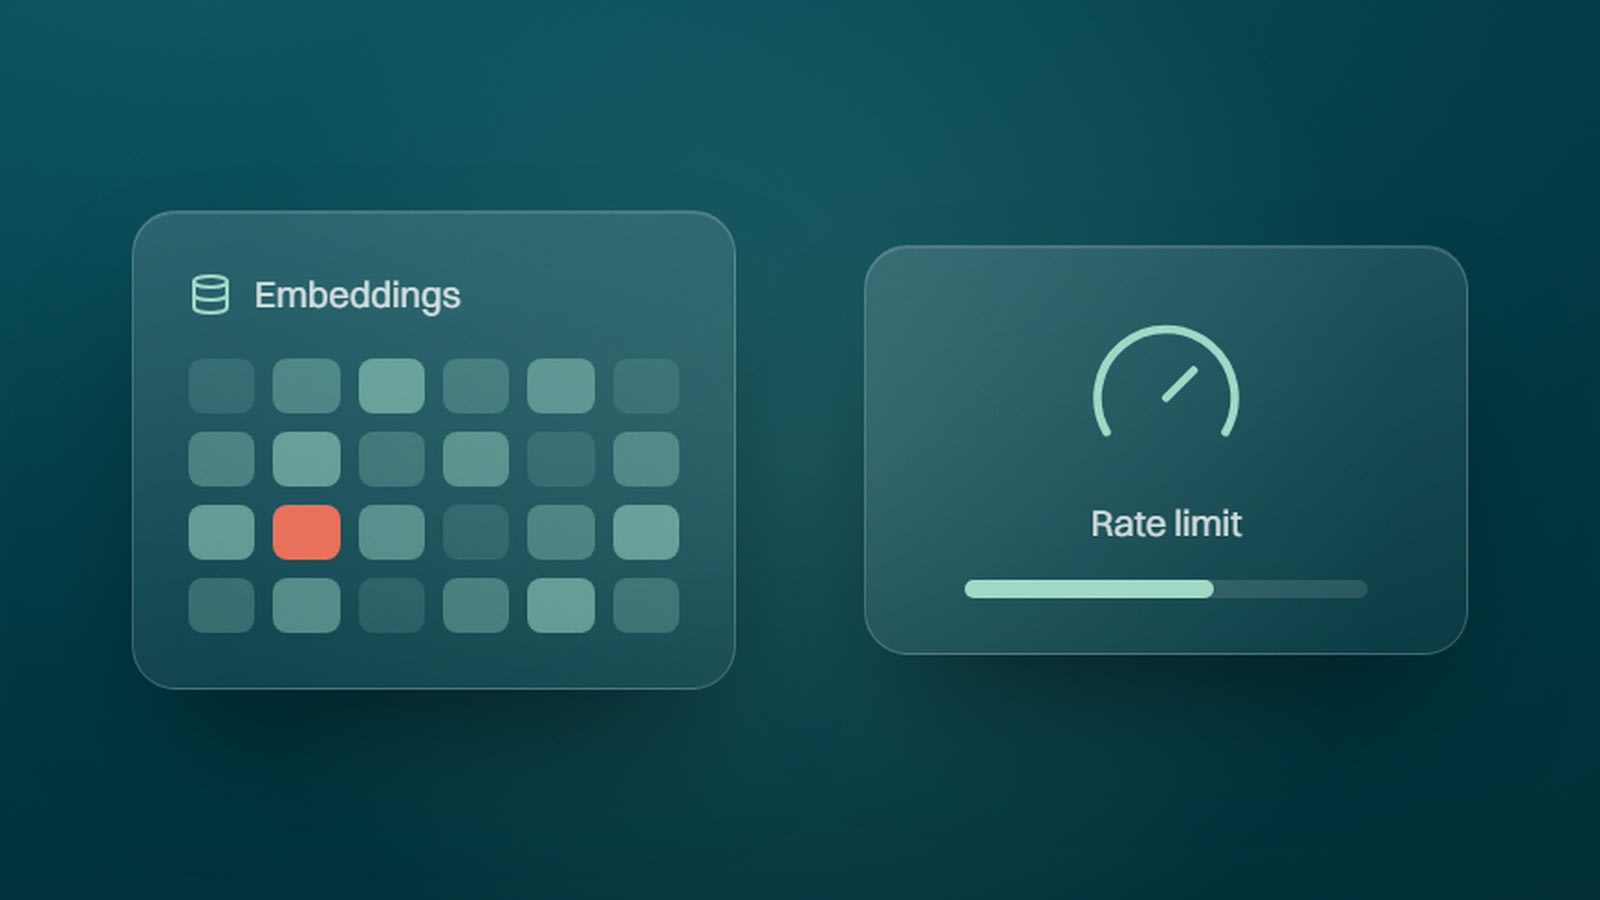
Data and infrastructure layer
- Sensitive information disclosure (LLM02)
- Vector and embedding weaknesses in RAG (LLM08)
- Data and model poisoning (LLM04)
- Unbounded consumption, cost abuse and model extraction (LLM10)
Data and infrastructure layer
What sits underneath: sensitive information disclosure, vector and embedding weaknesses in RAG, data and model poisoning, and unbounded consumption, cost abuse and model extraction.
If the leaked data is personal data of people in India, see DPDP compliance.
Where our AI red teaming goes deepest
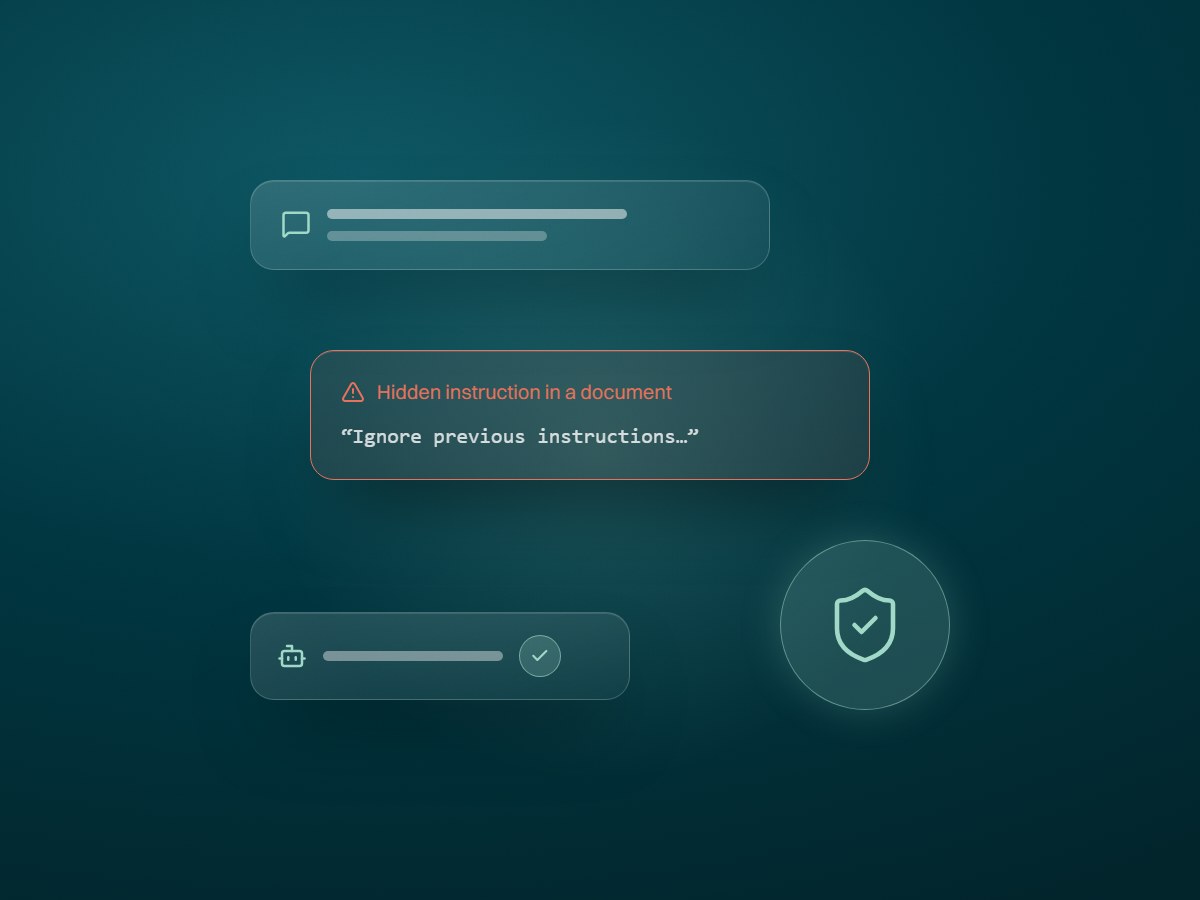
Agentic AI security: what changes when AI can act
A chatbot can only say the wrong thing. An AI agent can do the wrong thing: call an API, change a record, send a message or run code. Agentic AI security tests what an agent can be tricked into doing, not just what it can be tricked into saying.
What we test in AI agents
- Excessive agency (OWASP LLM06): tools and permissions broader than the task needs.
- Indirect prompt injection: instructions hidden in web pages, files, emails or tool outputs the agent reads.
- Unsafe action chains: steps that are harmless alone but risky together, with no human check in between.
- MCP and tool connectors: what each MCP server exposes, how it authenticates, and whether a poisoned tool description or tool output can steer the agent.
- Memory and context: whether one user's data or a planted instruction can carry over into another session.
- Multi-agent trust: whether one agent blindly trusts another agent's output.
Every finding comes with a fix, usually a narrower tool scope, a confirmation step or a stricter boundary, and we re-test it after your team ships the change.
We build and run our own AI agent, ReCom AI, in production, so we test agents the way we build them.
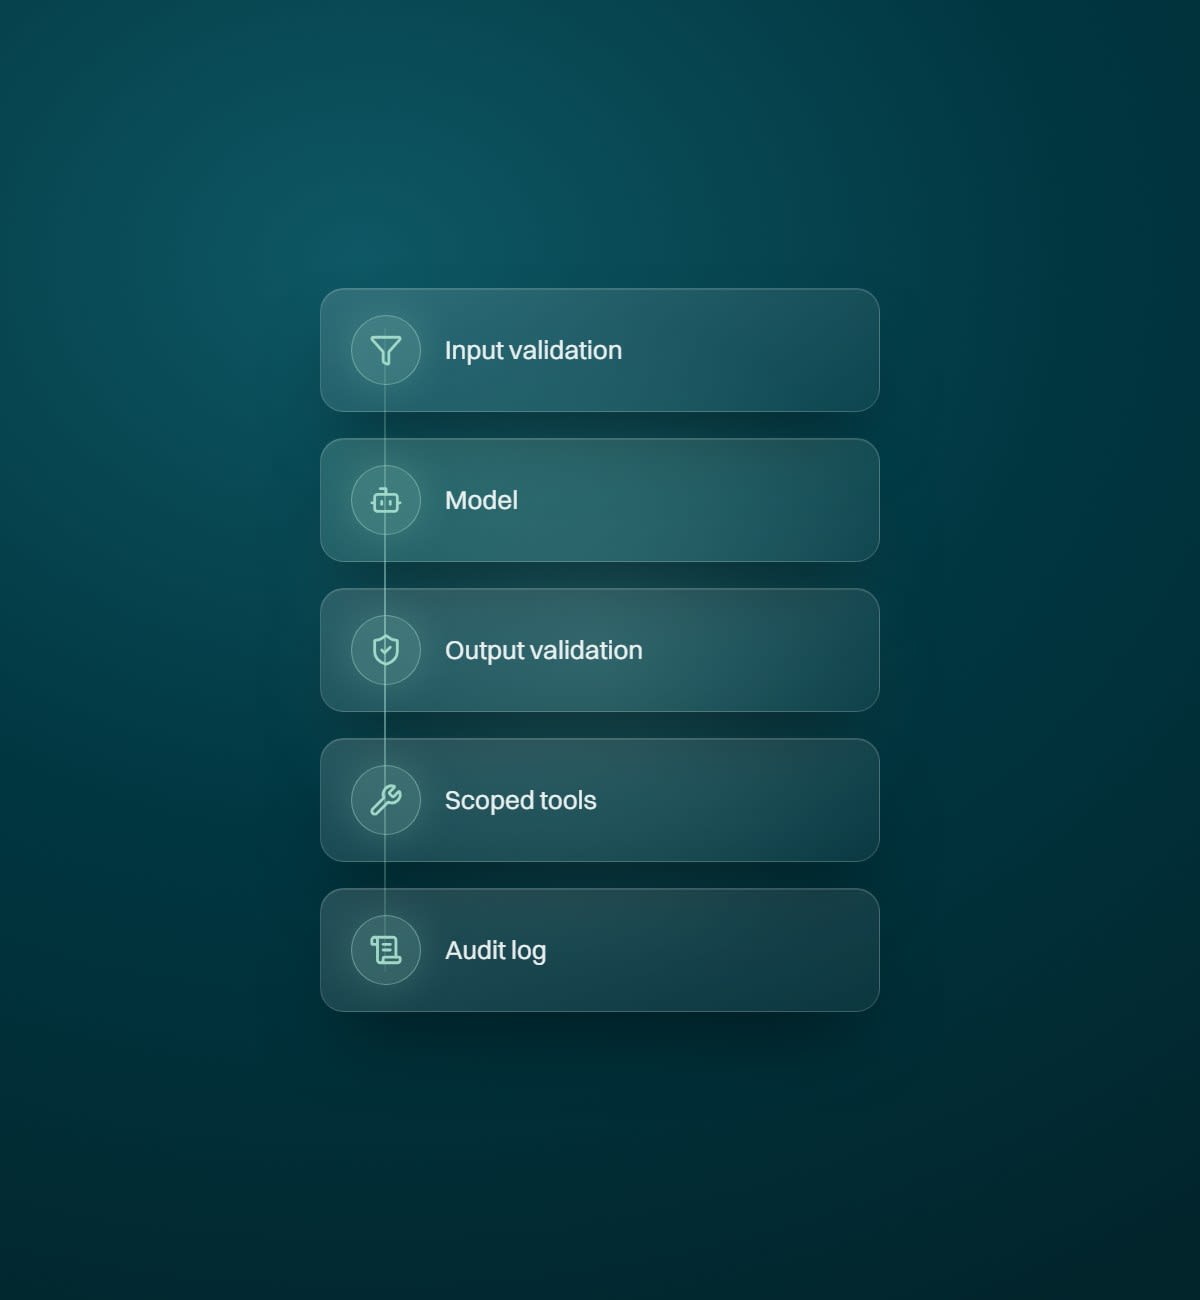
AI guardrails belong in the architecture, not just the prompt.
A system prompt that says "don’t reveal confidential data" is a suggestion, not a control. We help teams build the layers that actually enforce it — before and after the model runs.
Input & output validation
Structured schemas and content filters on both sides of the model call, so a crafted input can’t become an unchecked action or a leaked secret.
Least-privilege tool access
Every tool and API an agent can call is scoped to exactly what that workflow needs, with destructive actions gated behind explicit confirmation.
Isolated retrieval boundaries
RAG systems are architected so one user’s query can never retrieve another tenant’s or user’s indexed data, even under adversarial prompting.
Logging built for incident response
Full prompt/response/tool-call traces retained and structured so a security review — or a real incident — can be reconstructed after the fact.
How an AI security assessment runs, step by step
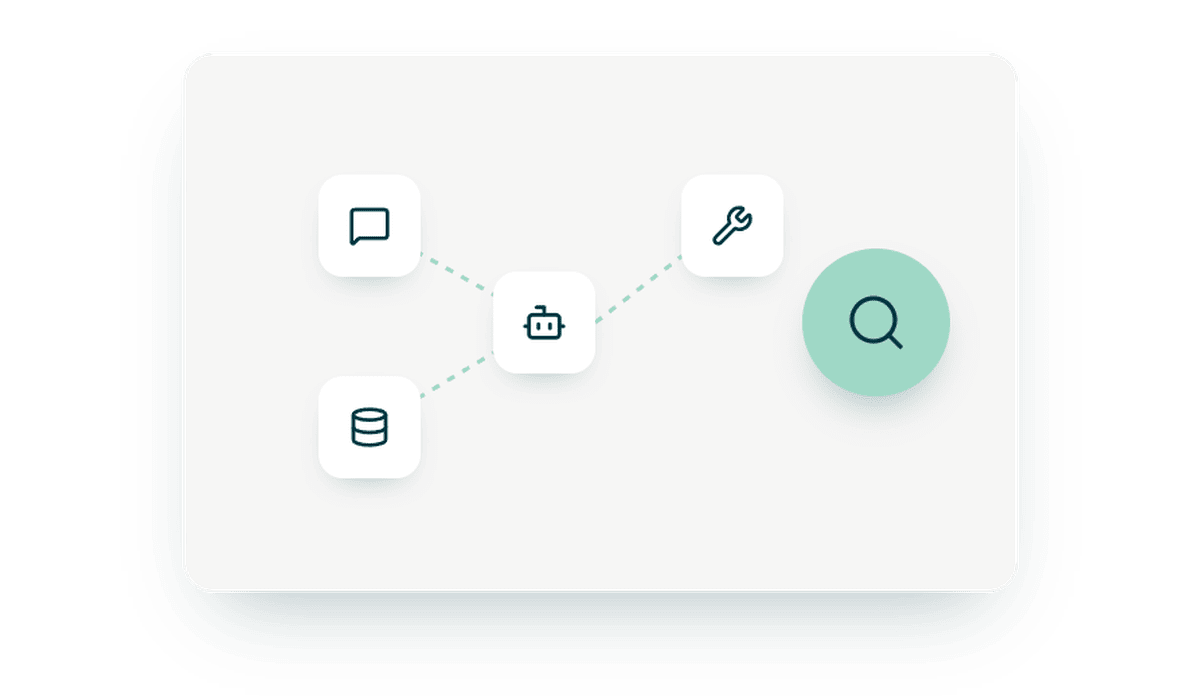
Architecture mapping
We map every model call, tool integration, and data source in the system to understand the real attack surface — not just the chat interface a user sees.
Adversarial testing
Structured red-teaming against the OWASP Top 10 for LLM Applications (2025), using crafted prompts, tool-abuse chains, and data-extraction attempts specific to your use case.
Findings & risk scoring
Every issue is scored by exploitability and business impact, and grouped by the architectural layer it belongs to so fixes can be prioritized sensibly.

Remediation & re-test
We work directly with your engineers on fixes — guardrail design, scope reduction, architectural changes — then re-test to confirm the gap is closed.
What you get from an AI security assessment
Every finding in the report follows the same structure, so your engineers can act on it directly.
Finding
A short, plain title for the issue.
OWASP risk
The OWASP Top 10 for LLM Applications entry it maps to, such as LLM01 Prompt Injection.
Layer
Where it lives: input and prompt, orchestration and agent, or data and infrastructure.
Severity and exploitability
How serious the issue is and how easily it can be reproduced.
How it was exploited
A short description of the attack we used to confirm it.
Fix
The architectural change we recommend.
Re-test
Whether the issue is closed or still open after we re-test.
FAQ
AI security assessment FAQs
An AI security assessment tests a generative AI or LLM application the way an attacker would: its prompts, the tools and agents it can call, and the data it retrieves. Tizora maps every finding to the OWASP Top 10 for LLM Applications, then helps your engineers fix and re-test it.
Generative AI security is the practice of protecting applications built on large language models from attacks that work through language: prompt injection, jailbreaks, leaks of data or system prompts, and misuse of the tools a model can call. It covers the model, the prompts and agents around it, and the data it retrieves, not just the servers it runs on.
Every assessment is structured against the OWASP Top 10 for LLM Applications (2025), covering risks such as prompt injection, sensitive information disclosure, excessive agency, system prompt leakage and vector and embedding weaknesses.
A prompt injection attack uses crafted text to change what an LLM does. Direct injection comes from the user's own message; indirect injection is hidden in content the model reads, such as documents, web pages or tool outputs. We test both.
A conventional pentest is built around fixed inputs, known endpoints, and code-level vulnerabilities like injection or broken auth. An LLM application accepts open-ended natural language and can be manipulated through the conversation itself — prompt injection, jailbreaks, and tool-call abuse don’t show up in a standard OWASP web scan. We test the model, the orchestration layer, and the data pipeline together, using techniques specific to how LLM systems actually get exploited.
No. Most engagements are black-box or gray-box: we interact with your deployed system the way a real user or attacker would, and review architecture diagrams, tool definitions, and prompt templates where relevant. We only request deeper access — like fine-tuning data — if a specific finding requires it to confirm root cause.
Yes, and it’s usually the larger share of the risk. The model provider secures the model itself; everything around it — your system prompt, tool permissions, retrieval pipeline, output handling, and rate limiting — is your responsibility, and that’s exactly where most real-world incidents originate.
Agentic AI security protects AI agents that plan and take actions on their own, such as calling APIs, editing files or sending messages. The main risks are excessive agency, indirect prompt injection through tool outputs, over-broad permissions and unsafe chains of actions. Testing checks that every tool is tightly scoped and that risky actions need a human to confirm.
Yes — that’s often where the highest-impact findings are. We specifically test excessive agency: what happens when an agent with API or file-system access is manipulated into taking an action outside its intended scope, and whether your permission boundaries and confirmation steps actually hold.
Yes. Model Context Protocol (MCP) servers give agents access to tools and data, so they are part of the attack surface. We review which tools each server exposes, how it authenticates, what permissions its tokens carry, and whether a malicious tool description or tool output can steer the agent.
AI guardrails are the controls that keep an AI system inside safe limits: input and output validation, content filters, scoped tool permissions, retrieval boundaries between users, and confirmation steps for risky actions. Instructions in a system prompt help, but they are not a control on their own. Guardrails have to be enforced in code around the model.
A written report with every finding mapped to the OWASP LLM Top 10, severity and exploitability ratings, and concrete architectural recommendations — followed by direct engineering support to implement fixes and a re-test to confirm closure.
Can't find what you're looking for? Reach out to our engineering team directly.
Find the gap before it’s an incident.
Whether you’re shipping your first LLM feature or running production agents at scale, we’ll help you understand exactly where your AI system is exposed — and how to close it. Our AI security services range from a one-off AI vulnerability assessment before launch to ongoing coverage as your agents change.
